TL;DR
AI data collection is the process of gathering and preparing data for machine learning models.
Data comes from six main methods: web scraping, APIs, first-party user data, sensors, existing datasets and synthetic data.
Raw data isn’t usable until it’s cleaned, deduplicated and often labeled.
Public data is usually fair game. Personal data and data behind logins come with legal limits.
Quick Answer: AI data collection is the process of gathering raw text, images, audio, video or records and preparing them to train, test and improve machine learning models. Teams collect it through web scraping, APIs, user interactions, sensors, public datasets and synthetic generation, then clean and label it before training.
What is AI data collection
It’s the first step in building any machine learning model. A model can only learn patterns in its examples, so the data you collect determines what it can do and where it fails.
What makes it different from ordinary data gathering is the goal. A sales report needs accurate records. A model needs volume, variety and balance: thousands or millions of examples that cover the real situations it will face, without one source drowning out the rest. That’s why data collection in machine learning is usually an ongoing process rather than a one-off export.
Is it the same as training data
Not quite. Training data is the result: the cleaned, labeled examples a model learns from. Collection is the work of finding, gathering and preparing those examples. Most teams also hold back separate validation and test data to check the model on examples it hasn’t seen.
How does AI collect data
AI doesn’t collect data on its own. People and pipelines collect it, using six main methods.
Method | What it gathers | Typical example |
Web scraping and crawling | Public pages, listings, reviews, articles | Price data for a forecasting model |
APIs | Structured data a platform chooses to share | Posts or product data from an official API |
First-party data | Clicks, searches, purchases, support chats | A store’s own recommendation engine |
Sensors and devices | Camera frames, GPS, wearable and machine readings | Self-driving and factory-inspection models |
Existing datasets | Open or licensed collections | Training an image model on a public image set |
Synthetic data | Examples generated by software or other models | Rare fraud cases that real data lacks |
Most production models combine several methods. A customer-support chatbot might mix the company’s own chat logs, public help articles and synthetic conversations covering rare questions.
Where does AI get its data from
The biggest single source is the public web. Common Crawl, a nonprofit, has maintained a free, open archive of web crawl data since 2007, and researchers widely use it in language-model research. On top of that, AI teams draw on:
Licensed content: news archives, books, stock images and code, used under paid agreements
Open datasets: research collections released for public use
User interactions: feedback, ratings and conversations, where the product’s privacy terms allow it
Human-made data: experts and annotators who write, rank or label examples
Training data for generative AI leans heavily on text, code and images from the first two sources. Smaller task-specific models lean more on a company’s own first-party data.
Expert Insight: Most data projects don’t stall on the scraping code. They stall on blocked requests and patchy coverage. If your crawler reaches 70% of a site’s pages and silently fails on the rest, the model learns a skewed picture without anyone noticing.
What types of data does AI collect
Data type | Examples | What it powers |
Structured | Prices, dates, transactions, sensor readings | Forecasting, pricing and fraud models |
Unstructured | Free text, images, audio, video | Language models, computer vision, speech recognition |
Semi-structured | JSON, XML, chat logs, web pages | Chatbots, search ranking, recommendation systems |
What does the AI data collection pipeline look like
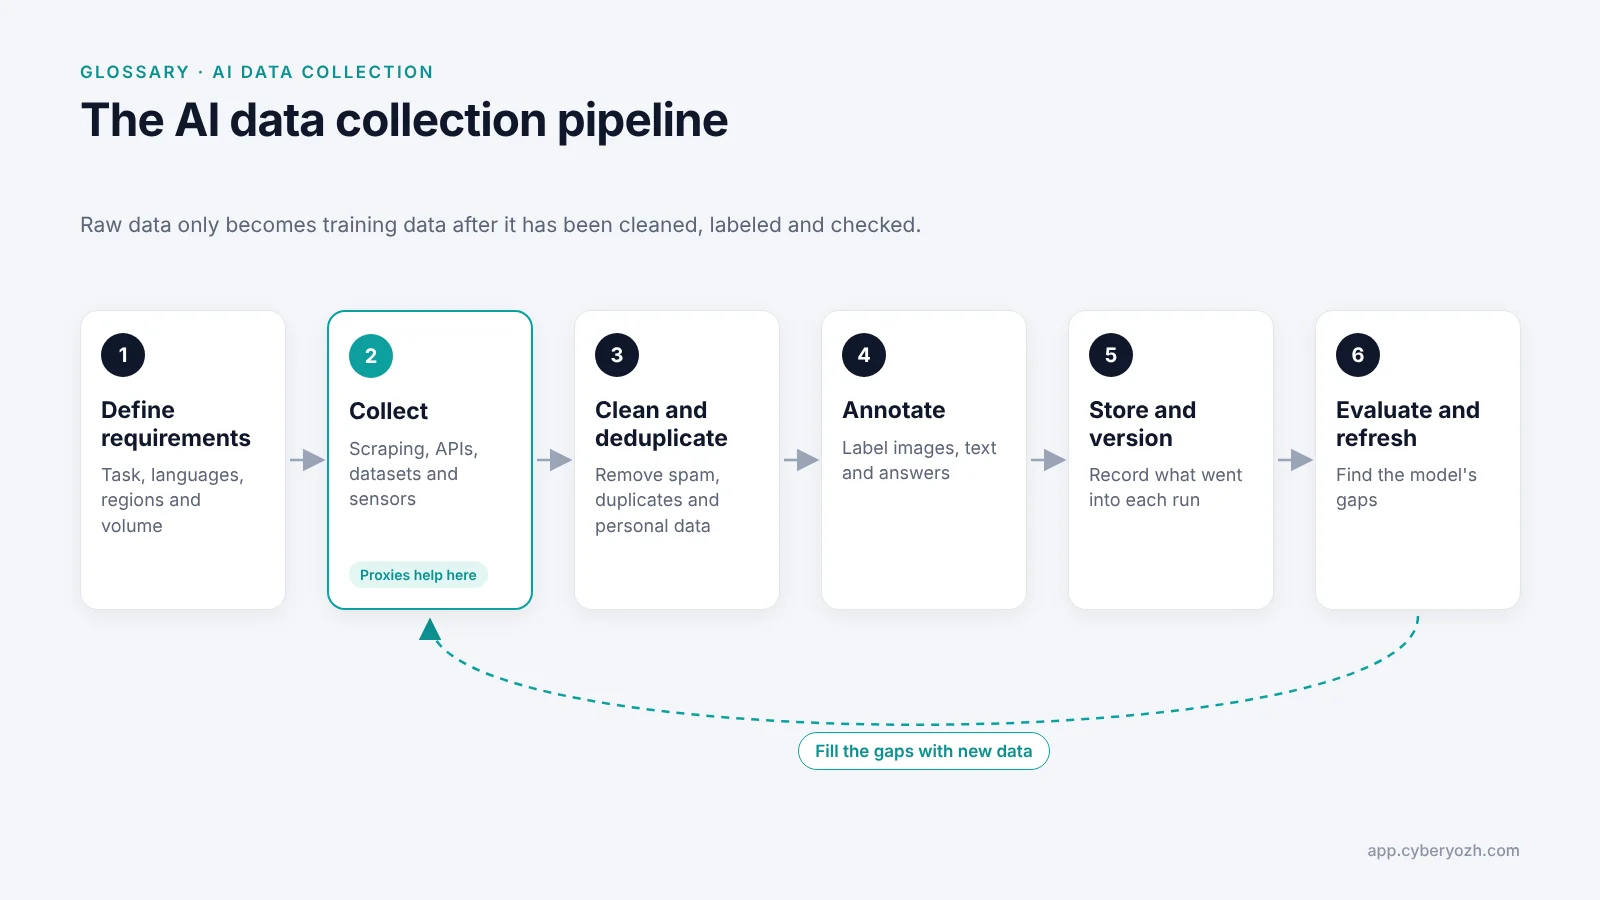
Define requirements: what the model must do, which languages or regions it covers and how much data it needs
Collect: run scrapers, API pulls and dataset downloads
Clean and deduplicate: remove broken pages, spam, near-duplicates and personal data you shouldn’t keep
Annotate: label examples where needed, such as tagging images or rating answers
Store and version: keep a record of what went into each training run
Evaluate and refresh: check the model, find its gaps and collect new data to fill them
Data collection and annotation are often confused. Collection gathers the raw material. Annotation adds the labels that tell a model what each example means.
Common Mistake: Collecting data from only one location. Prices, search results and even page text change by country. A dataset scraped entirely from US IP addresses teaches a model the US version of the web and calls it the whole web.
Is AI data collection legal
Usually, when it sticks to public data and respects privacy law. Three lines matter most:
Public vs. private. In the long-running hiQ v. LinkedIn case, a US appeals court found that scraping publicly accessible pages likely doesn’t break the Computer Fraud and Abuse Act (EFF’s case summary). Terms of service can still create contract claims, which is how that dispute ultimately went against hiQ.
Personal data. Names, photos and contact details fall under privacy laws such as the GDPR in Europe and the CCPA in California, even when they’re publicly visible.
Copyright. Several lawsuits over training models on copyrighted work are still open, so licensed or openly licensed sources carry less risk.
Warning: Don’t collect data from behind a login or bypass a site’s access controls. That’s where most legal risk sits. This page is general information, not legal advice, so check with a lawyer before collecting personal data at scale.
For a practical checklist, see our guide to ethical web scraping.
Why does web data collection need proxies
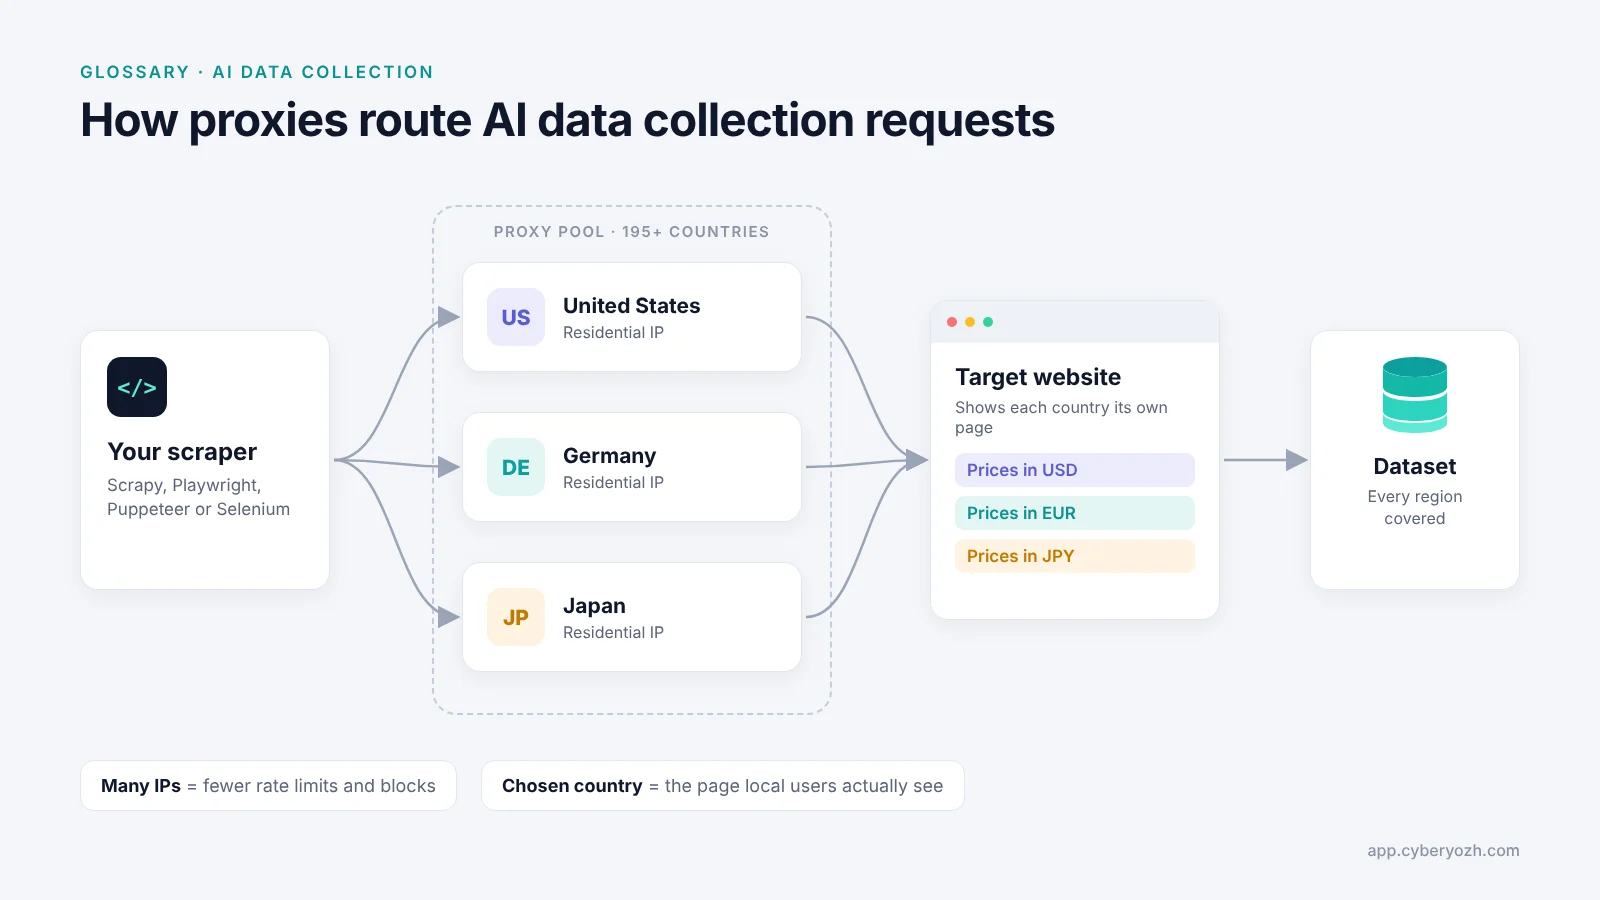
Only one of the six methods needs them: collecting public web data at scale. If you send thousands of requests from one IP address, sites will rate-limit or block you within minutes. You also only see the version of each page shown to your own country.
Proxies spread requests across many IP addresses and let you choose the country each request comes from. Here’s how CyberYozh proxy types fit common AI data collection jobs:
Collection job | Best proxy type | Price from |
Large-scale crawling of public pages | $2/GB | |
High-volume collection from lightly protected sites | Datacenter, unlimited traffic | $1.77/month (shared) |
Sessions that must keep one IP, such as paginated results | $5.29/month | |
Mobile-only content and the strictest sites | See the catalog |
100M+ residential IPs in 195+ countries for balanced, location-specific datasets
Full API access with support for Selenium, Playwright, Puppeteer and Scrapy
HTTP(S) and SOCKS5 on every proxy type
Rated 4.7+ Excellent on Trustpilot
Pro Tip: Run a sample of your IPs through CyberYozh’s free IP Fraud Score checker before a big crawl. Swapping out flagged addresses first costs minutes. Debugging a half-blocked crawl afterwards costs days.
Building a pipeline? See our proxies for AI data collection, or compare providers in our roundup of data collection services.
Collect cleaner, location-balanced data. Browse the CyberYozh proxy catalog →