Real mobile LTE / 5G networks
Run AI agents through real carrier networks with unlimited mobile traffic and dedicated channels.
- Real LTE / 5G carrier networks
- Manual and API IP rotation
- High-trust environments
- Stable AI sessions
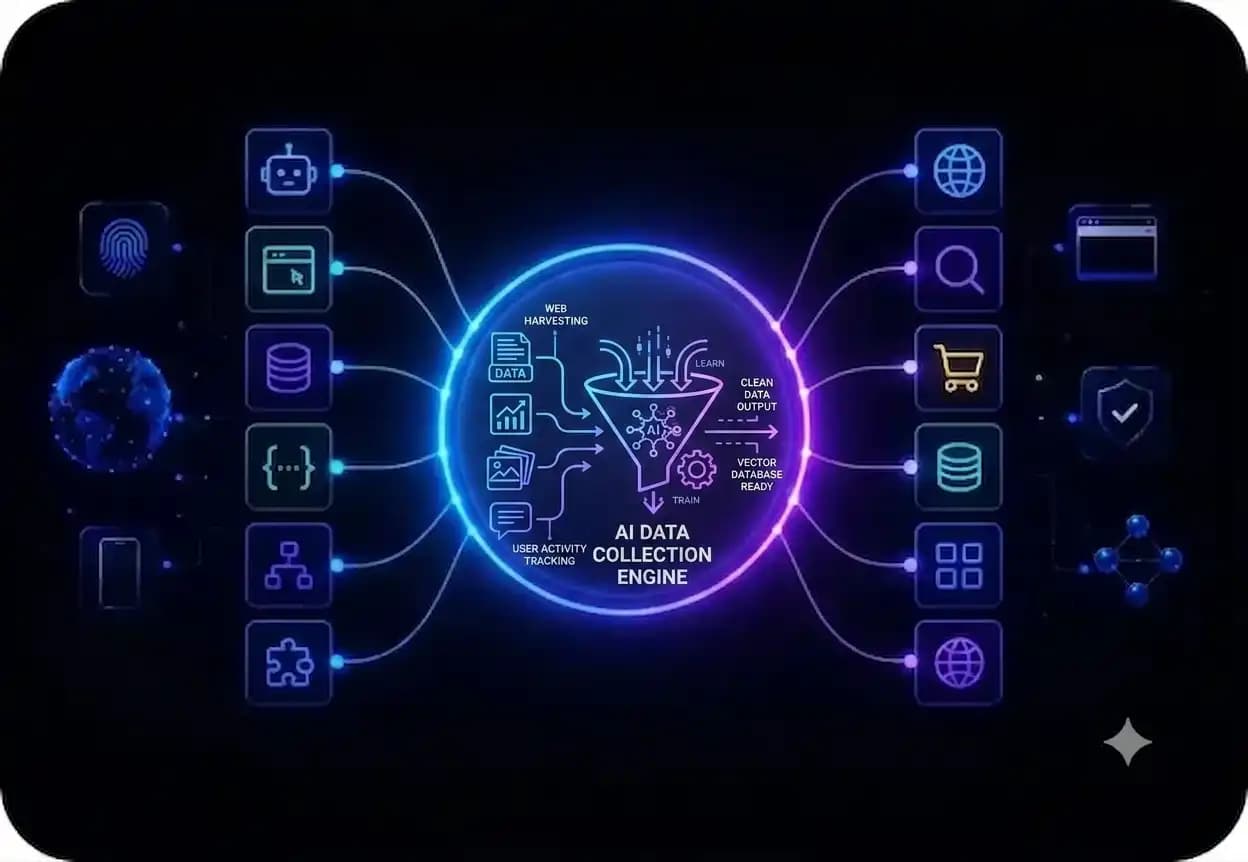
Power AI training, RAG pipelines, and market research with 100M+ residential, mobile LTE/5G, and datacenter IPs across 195+ countries. City-level targeting, flexible rotation, and 24-hour sticky sessions for fewer rate limits and blocked requests – so your pipelines deliver usable data without babysitting.

Connect proxies to your AI data collection stack through API access to keep data pipelines running. Compatible with Playwright, Puppeteer, Selenium, Scrapy, and custom scripts.

Set up a proxy and start collecting web data without managing complex infrastructure. Adjust data collection behavior with flexible IP rotation and sticky sessions as your datasets and workloads grow.

Proxies with granular city- and zip-level targeting let you collect localized data without distortions. Get accurate web data for AI training, market research, and price monitoring.

Maintain stable data collection with OS fingerprint options alongside proxy infrastructure to maintain consistent device signals. Keep network parameters aligned with fingerprint settings and verify IP quality before running large-scale data collection.
Run AI agents through real carrier networks with unlimited mobile traffic and dedicated channels.

Reduce workflow interruptions with CAPTCHA solving support and validation tools built for automation.

Manage proxies, SMS activation, fingerprinting, fraud checks, and integrations from one environment.
CyberYozh’s proxy infrastructure enables large-scale data collection for AI training, market research, and machine learning workflows. The network combines 100M+ residential IPs, mobile LTE/5G proxies, and datacenter proxies with precise targeting, flexible rotation, sticky sessions up to 24 hours, and IP verification tools. With monitored IP quality, fingerprinting options, and virtual numbers, CyberYozh provides a reliable infrastructure to collect data without distortions, reduce interruptions, and scale AI pipelines across global markets.
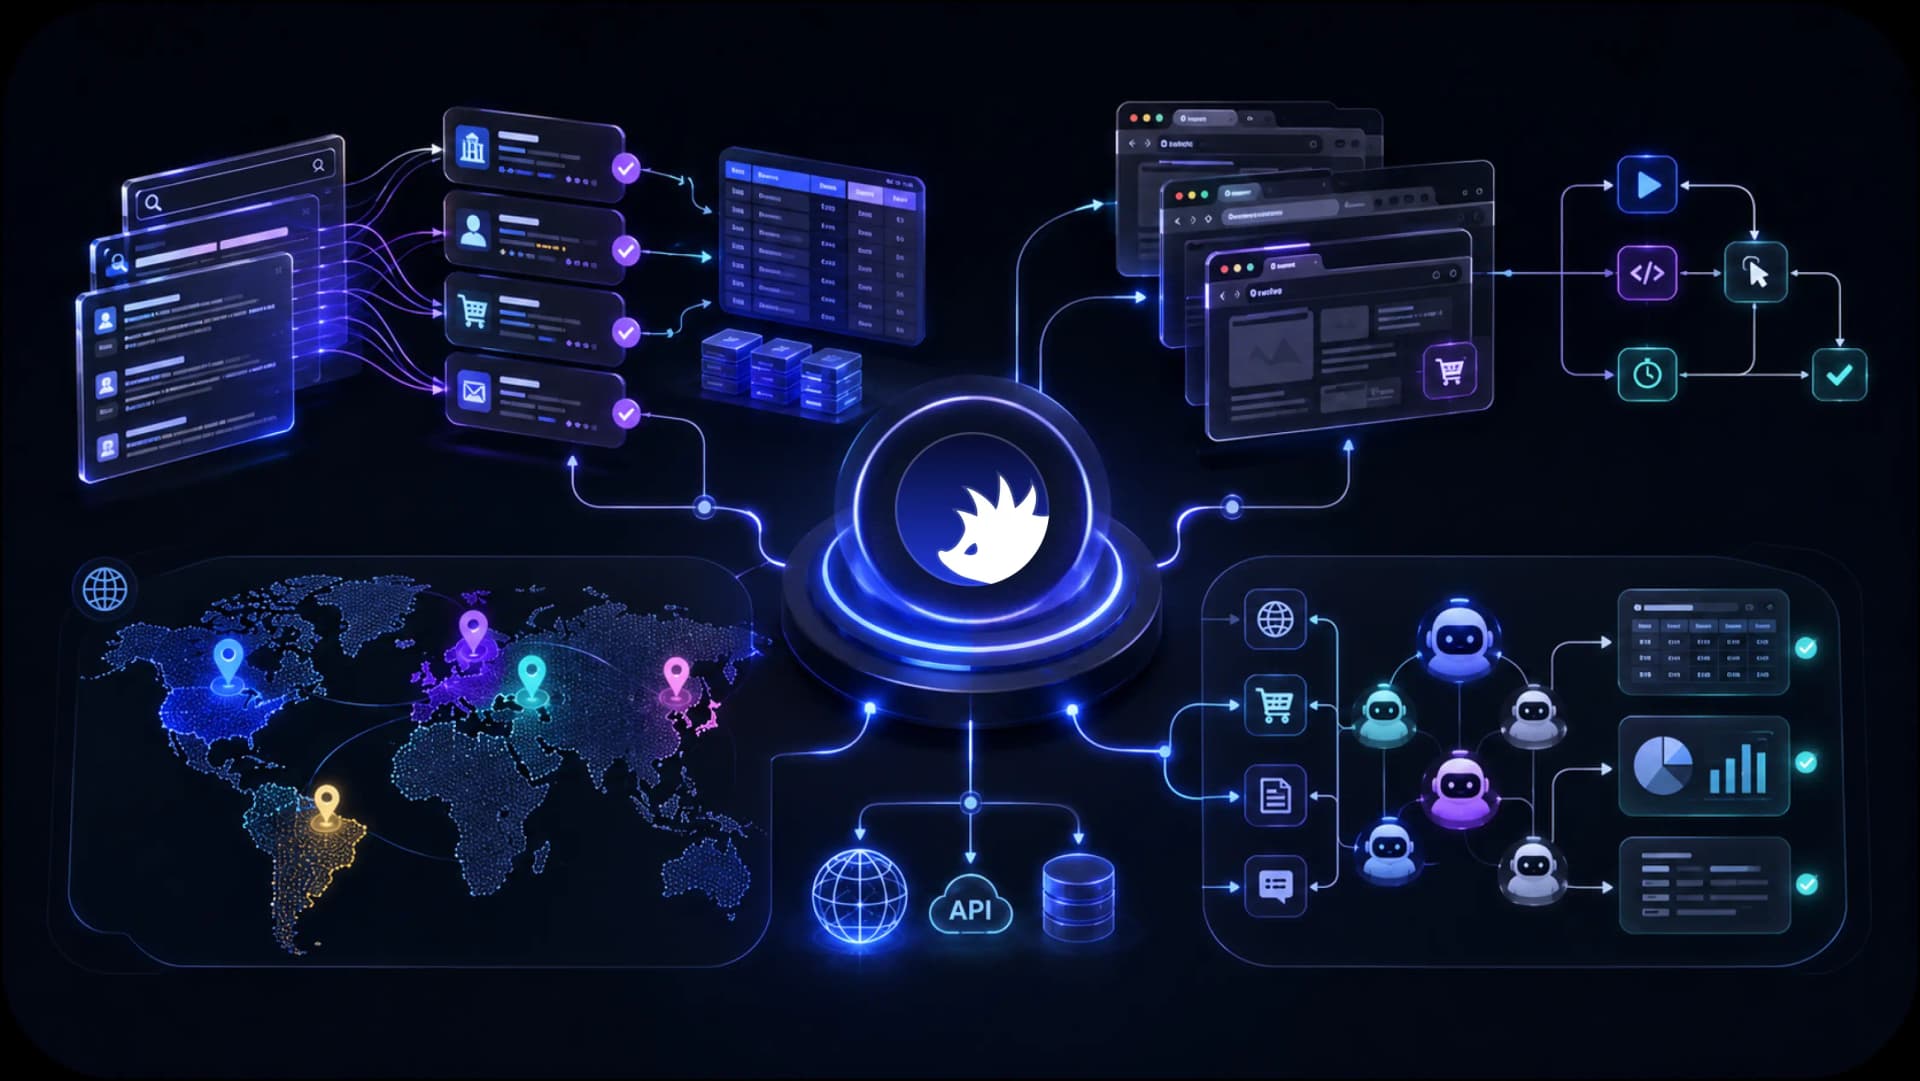
Access localized search results, marketplaces, public web data, and regional content across 195+ countries for AI agents, scraping systems, and autonomous workflows.
CyberYozh combines the infrastructure AI teams need to collect data, automate workflows, access regional content, and scale execution environments. From mobile LTE / 5G and residential proxies to browser automation support, fingerprinting, fraud checks, and Android cloud phones, everything is designed to support AI workflows from a single platform.
AI web scraping
AI browser automation
AI data collection
AI agent execution
Mobile AI workflows
Regional AI access
See how CyberYozh works in practice through real workflows, platform features, and infrastructure examples. Explore the dashboard, integrations, execution environments, and tools available for AI teams and automation projects.
Proxies are the critical infrastructure that ensures your AI receives fresh, diverse, and uninterrupted data streams for your task. Whether you are developing AI applications, training machine learning models or monitoring competitor pricing and search rankings, here’s what it helps you achieve.
Fewer IP bans and rate limits: Websites aggressively block IPs that send too many requests. With rotating IPs, you can run ensuring uninterrupted high-volume scraping without triggering anti-bot defenses.
Access localised content: Proxies with geo-targeting let you collect localized search results, social feeds, and regional pricing, giving your model a true worldwide perspective.
Defeat anti-bot measures: Modern sites use advanced fingerprinting and CAPTCHAs. Premium proxies look like real users to the platforms, ensuring you pass these checks and capture the data you need.
Stability and scale: Data collection can't afford downtime. A robust proxy network with load balancing keeps your pipelines running even during peak demand.
Protect your infrastructure: Proxy servers act as a buffer, shielding your origin IP and internal systems from malicious actors and legal exposure.
Different AI data collection workflows create different infrastructure demands, from localized SERP collection to real-time pricing data and browser-based AI agents.
A team scraping millions of web pages for an LLM training corpus hit rate limits within hours on a single IP. Pipelines stalled with incomplete batches, and engineers wasted days unblocking addresses instead of building models. They switched to datacenter AI training data proxies, spreading requests across thousands of IPs to stay below detection thresholds.
⚡ Result: continuous full-throughput scraping, daily targets met, and engineering time back on model development.
Yozh Scraper — free, open-source, Playwright-based — pairs automated extraction with CyberYozh's proxy network, so you control proxy type, GEO, rotation, and sessions in one workflow.
An SEO analytics team tracking keyword rankings across dozens of countries faced instant CAPTCHAs and inconsistent geo-results from Google and Bing. This led to unreliable client data and poor decisions. They moved to rotating residential proxies for SERP data collection distributing query volume across a large IP pool.
⚡ Result: accurate, country-specific SERP data at scale with minimal CAPTCHA interruptions and rankings clients could trust.
Powered by API: CyberYozh's API gives direct programmatic control over rotation and country/region targeting, plugging straight into existing scraping stacks like Scrapy, Playwright, or Postman — no manual proxy list management needed.
A dynamic pricing engine needed to monitor live competitor pricing from Amazon and Walmart, but platforms detected automation within minutes, serving distorted prices or blocking IPs. The AI made decisions on stale data. They switched to residential rotating proxies, making requests look like real local shoppers.
⚡Result: real-time, accurate competitive pricing for the AI, enabling instant bid and promotion adjustments instead of reacting to yesterday's numbers.
A team deploying browser-based AI agents for multi-step tasks (logins, forms, flight bookings) kept getting blocked mid-process. Sites fingerprinted automation frameworks and flagged shifting request patterns; basic IP rotation wasn't enough to complete a full workflow. They used a high-trust mobile proxy for AI agents with OS fingerprint options, giving each agent one stable identity per task.
⚡Result: reliable multi-step completion and a success rate that replaced constant retries and failures.
A team running a RAG system for financial research kept surfacing old or cached answers instead of live pages. They moved retrieval traffic onto rotating residential proxies with short sticky sessions, so each query pulled a fresh, uncached view of the source page.
⚡ Result: retrieval responses reflecting current web content instead of caches, with fewer blocks interrupting the pipeline.
⭐ Read more about the RAG proxy network
A team building an AI-powered content aggregator needed to pull articles, listings, and product specs from hundreds of sites. A single proxy type worked on some sites and got instantly blocked on others, forcing engineers to maintain separate workarounds. They moved to a mixed proxy setup (datacenter for permissive sites, rotating residential for protected ones) routed through a single API so the scraper could switch proxy type per target.
⚡ Result: one scraping pipeline for all sources, with fewer per-site maintenance fixes and consistent data delivery.
⭐ Learn more about AI web scraping proxies
Not all proxies are built the same. Each type serves a distinct purpose in the AI data pipeline:
Best for: Works as AI training data proxy and also for web research, SERP tracking, and e-commerce monitoring. Residential proxies for machine learning are also a popular choice.
Why: Real ISP-assigned IPs with organic browsing patterns provide higher trust scores, making them effective against sophisticated anti-bot systems like Cloudflare and DataDome.
Best for: Mobile app data, social platform scraping (Instagram, TikTok, X), and ad verification.
Why: Carrier-assigned IPs carry the strongest network reputation. Mobile IPs are rarely blacklisted because they represent actual consumer devices with rotating network cells.
Best for: High-speed public data collection, bulk crawling for LLM training, and price aggregation.
Why: Servers deliver fast throughput at the lowest cost per request. Ideal when volume matters more than evading aggressive blockers.
Operator takeaway: Rotating residential proxies are the default for most AI collection tasks — not just to avoid blocks, but to inject geographic and behavioral diversity into your training data, improving model generalization. However, if you need logged-in sessions, go for static residential or mobile.
Yes. Collecting publicly available web data for AI training, market research, or price monitoring is standard practice, and CyberYozh's infrastructure is built to support it responsibly.
Before collecting:
Check the source's Terms of Service and crawling rules
Identify whether personal data is involved
Collect only what your use case requires
Keep track of where and when the data was collected.
Define your sources. List the sites, APIs, or platforms you need data from, and note which ones are geo-restricted, rate-limited, or bot-protected.
Choose your proxy type. Datacenter for speed and volume, residential for sites with strong anti-bot detection, mobile for the highest-trust targets.
Select your GEO. Match proxy locations to the regions your sources serve, down to city level where localized results matter.
Configure rotation and sessions. Rotate per request for high-volume scraping, or hold a sticky session (up to 24 hours) when a task needs one consistent identity.
Connect via API. Plug proxy access into Scrapy, Playwright, Puppeteer, or Selenium with programmatic rotation and GEO targeting, no manual list management.
Collect. Run the pipeline against your defined sources using the configured proxy setup.
Feed the dataset. Route validated data into your AI training pipeline or application.
CyberYozh combines multiple proxy types, global coverage, and automation-ready controls so AI teams can match their collection infrastructure to dataset size, geography, and workflow requirements.
Residential rotating proxies: 100M+ residential IPs across 195+ countries. Flexible rotation, 24-hour sticky sessions, and free geo-targeting for consistent collection of undistorted data.
Real mobile LTE/5G proxies (unlimited bandwidth): Collect mobile-specific or location-dependent data through real carrier networks without overpaying per GB.
API and automation support: Integrate with AI data pipelines, custom scripts, and tools such as Playwright, Puppeteer, Selenium, Postman, and Scrapy.
Flexible rotation: choose between rotation per-request and sticky sessions to adapt collection behavior to different datasets and sources.
One-in-all platform with proxies, SMS verification, virtual payment cards and IP quality check tools for comfortable scaling.
Responsive client support 24/7 in 7 languages via e-mail and Telegram.