A web scraping proxy is a server that sits between your scraper and the websites it visits, sending requests through other IP addresses. The site sees the proxy’s IP instead of yours, so you can collect public data at scale without being rate-limited or blocked.
Key takeaways
A web scraping proxy hides your real IP and spreads requests across many addresses
Residential, mobile, datacenter, and ISP proxies suit different targets
A proxy improves web scraping anonymity, but it doesn’t hide your browser fingerprint on its own
New to the topic? Read what web scraping is first.
How does a web scraping proxy work
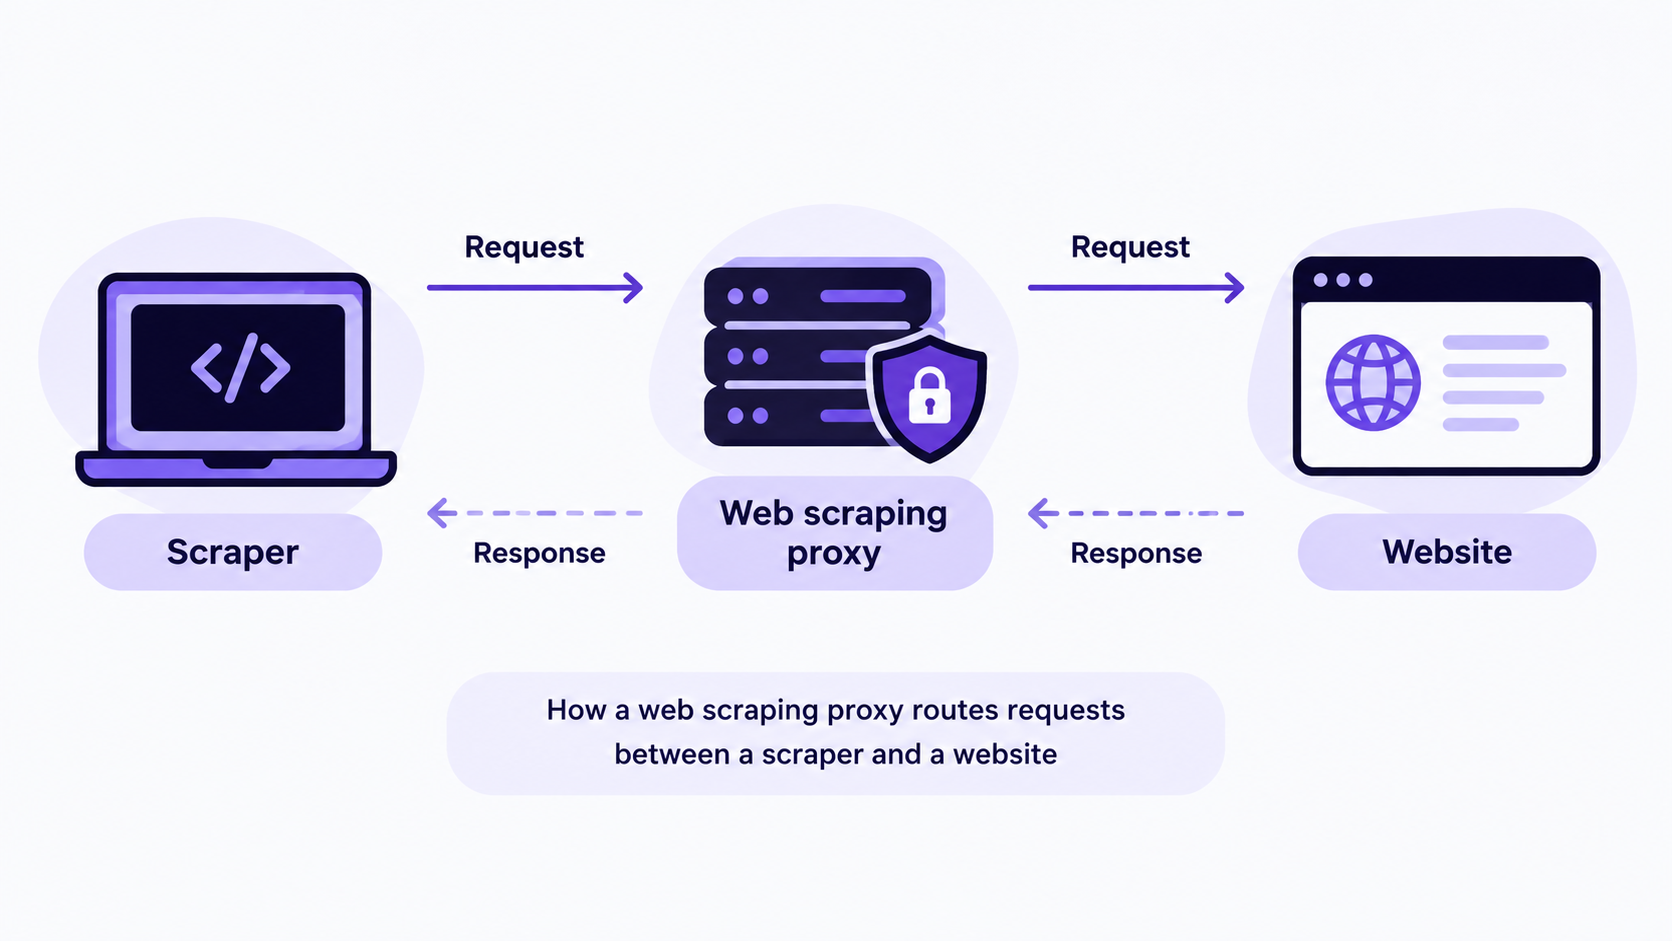
Your scraper sends a request to the proxy, not the website.
The proxy forwards it from one of its own IP addresses, often in the country or city you choose.
The website responds to the proxy, which passes the data back to your scraper.
In code, it’s usually one extra setting. Here’s how it looks in Python:
import requests


proxy = "http://USERNAME:PASSWORD@PROXY_HOST:PORT"

r = requests.get("https://httpbin.org/ip", proxies={"http": proxy, "https": proxy}, timeout=30)

print(r.json())  # shows the proxy's IP, not yours
Rotating proxies use a new IP for every request, while sticky sessions keep one IP for minutes or hours so you stay logged in. Our guide to rotating IP addresses explains when to use each.
Why do scrapers get blocked without a proxy
Websites flag traffic that doesn’t look human: too many requests from one IP, known datacenter ranges, or a time zone that doesn’t match the IP. The results are 403 errors, CAPTCHA walls and 429 responses, which MDN defines as “too many requests in a given amount of time.” If CAPTCHAs are your main problem, see how proxies help with CAPTCHAs.
Pro tip: A clean IP matters as much as the proxy type. Check its fraud score with the CyberYozh IP checker before a big job.
Types of web scraping proxies
Type | Where the IP comes from | Best for |
Rotating residential proxies | Real home internet connections | Most protected sites, such as e-commerce and search engines |
LTE/5G mobile proxies | Mobile carrier networks | The strictest sites and social platforms |
Datacenter proxies | Cloud servers | Public data and lightly protected sites |
Static residential (ISP) proxies | Fixed residential-grade IPs | Logged-in sessions and long monitoring jobs |
Compare providers in our guide to the best proxies for web scraping.
Web scraping anonymity: what a proxy hides and what it doesn’t
A proxy hides your real IP address, internet provider and location. That’s the foundation of web scraping anonymity, but websites check much more than IPs. If any other signal gives you away, sites can still link and block your requests.
Use this five-point checklist:
IP address: route every request through a proxy, and match its country to the data you need.
Browser fingerprint: sites read screen size, fonts and device details. Use a real or headless browser with a consistent, realistic profile.
Cookies and sessions: keep cookies separate for each session so blocking one session doesn’t expose the others.
Request timing: add random delays. Requests sent at perfectly even intervals look automated.
Headers: send a realistic User-Agent and an Accept-Language that matches your proxy’s country.
Common mistake: Assuming a proxy alone makes a scraper invisible. Identical fingerprints and robotic timing can still link your requests.
How to choose a web scraping proxy
Match the type to the target: residential for protected sites, datacenter for open data
Check session options: you’ll want both rotation and sticky sessions
Look for tools that save setup time: a free scraper and ready integrations cut days off your setup
Try it free first. CyberYozh’s open-source Yozh Scraper comes with ready presets for sites like Amazon and Google. Follow our Yozh Scraper setup guide to run your first scrape in minutes.
Scrape without blocks. Get a CyberYozh web scraping proxy with 100M+ residential IPs in 195+ countries and sticky sessions of up to 24 hours.