No-Code Web Scraper: Visual Data Extraction & AI Automation
Extracting market data is getting harder every day. You try to pull competitor prices or gather lead contacts, but the target server drops your connection. Building custom crawling scripts takes engineering time and demands constant maintenance. Modern automation platforms simplify no code data extraction. If you want to learn how to web scrape no code, visual interfaces let you extract information directly through your browser. They shift the technical work to artificial intelligence.
TL;DR: How to extract data from a website without code in under five minutes
Forget fragile Python scripts and manual DOM inspection. You can build a highly resilient data pipeline right now:
Select target web elements with a simple mouse click using a visual point-and-click interface.
Let the built-in AI repair broken extraction algorithms automatically whenever the target layout changes.
Delegate heavy JavaScript rendering and infinite scrolling to the native Playwright browser engine.
Route traffic through rotating residential networks to maintain stable access without anti-bot triggers.
Export clean data into CSV files or push LLM-ready Markdown datasets directly to your AI agents.
Why use a visual web scraping tool
Companies generate massive volumes of unstructured data in e-commerce daily. Large language models also require continuous training on fresh datasets. This demand pushed the global web scraping market to a 3.82 billion dollar valuation in 2025, with projections hitting 11.08 billion by 2034. Data collection used to be a strict engineering task.
Developers built complex browser automation frameworks using Puppeteer and Playwright. But scripts relying on hardcoded CSS selectors and XPath break immediately when websites deploy simple A/B tests or update their layout.
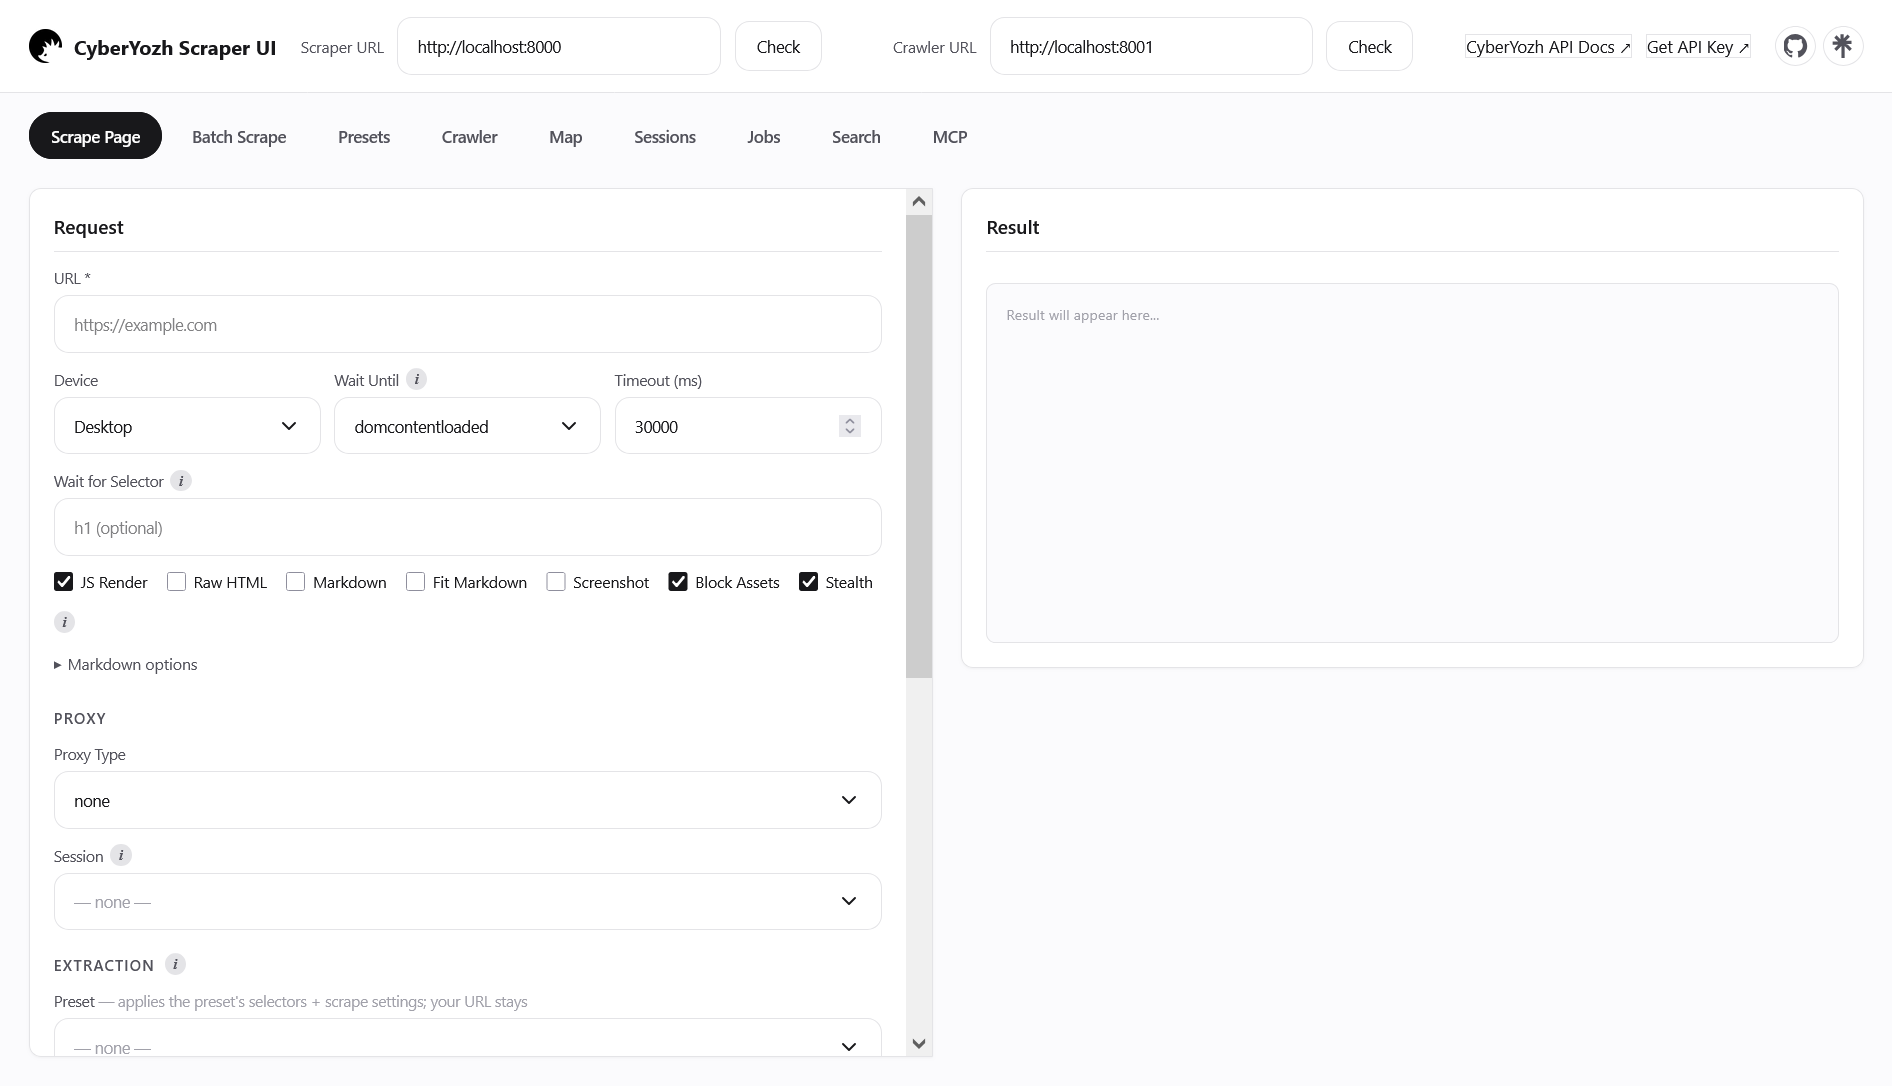
A modern no code web scraper abstracts this technical complexity. You get a visual point-and-click interface to map extraction algorithms instantly. The system handles pagination and performs dynamic JS rendering automatically.
👉 Mobile 4G and 5G proxies: overcome regional limits with premium networks
Real user case: E-commerce price tracking
Imagine running a competitive dropshipping business today. You need the best no code web scraper for ecommerce price tracking. You want to monitor competitor inventory across multiple marketplaces seamlessly.
You launch your visual web scraping tool. You input the target category URL. You click directly on a product title. You select the price tag. The system detects the recurring pattern immediately. It maps the DOM parsing logic for you. You click the run button.
The automated web scraper no code setup processes the queue. It extracts hundreds of items in minutes. Finally, you use the CSV export feature to push the structured JSON into your analytics dashboard. This no code web scraper performs natural browser interactions. It clicks buttons with randomized micro-delays. It scrolls pages just like a real human being.
Why do websites restrict automated requests
When you scrape dynamic websites without coding, enterprise firewalls often drop your connection. The restriction usually happens at the transport layer during the initial TLS Handshake.
Modern Web Application Firewalls analyze the ClientHello packet. The client sends this packet when establishing a protected connection. JA3 and JA4 algorithms hash these specific parameters. They deeply check the TLS version. They inspect the supported cipher suites and elliptic curves.
Standard Python or Node.js network libraries generate specific TLS fingerprints. These signatures differ radically from commercial browsers like Chrome or Safari. Traffic filters spot this network anomaly immediately. They reset your connection or require manual verification. Therefore, a reliable no code web scraper must base itself on a real browser engine. It must align TLS fingerprints exactly to maintain stable access.
👉 Residential ISP proxies: stable localized connections for extractions
The proxy infrastructure foundation
Matching TLS fingerprints means nothing without a clean IP address. Your no code web scraper requires a solid proxy infrastructure. The CyberYozh App ecosystem provides these exact scalable solutions. The platform maintains a strict zero-logs policy. It offers 24/7 technical support and highly private payment methods.
Professional routing infrastructure relies on strict technical metrics. Your proxy network must meet these exact criteria to ensure uninterrupted data collection:
Best Price: Pay-as-you-go billing without hidden fees.
High Speed: Low ping latency for rendering heavy Single-Page Applications.
Clean IP: High trust rates to eliminate anti-bot checks.
Many GEOs: Granular targeting down to specific ZIP codes across 195+ countries.
Traffic Rollover: Unused bandwidth carries over to the next billing period.
99% Success Rate: Intelligent load balancing guarantees request delivery.
99.99% Uptime: Fault-tolerant nodes keep long-running tasks active.
Free Test/Trial: Money-back guarantees to test compatibility.
Flexible Payments: Broad support for international cards and crypto.
UDP Support: Native handling of modern transport protocols.
Export Formats: Quick IP list generation (IP:PORT:USER:PASS).
Service Approvals: Pre-verified compatibility with major platforms like Amazon or Google.
Fast Support: 24/7 engineers available to resolve routing incidents.
Network Type | Key Feature | Ideal Deployment Scenario |
Mobile Proxies | Maximum Trust Rate (5G/LTE) | Social networks, mobile content |
Residential ISP | Static real provider address | Complex extraction, long sessions |
Rotating Residential | 100M+ pool, instant rotation | Massive marketplace price aggregation |
Datacenter Nodes | Low ping, 99.99% uptime | High-speed API scraping, SEO metrics |
Rotating residential proxies offer the best possible foundation for massive data aggregation. You get immediate access to over 100 million addresses. You pay only for the consumed bandwidth. You can easily configure sticky sessions lasting up to 24 hours. This intelligent setup ensures your data extraction blends perfectly with real human traffic.
👉 Rotating residential network: dynamic address rotation for scraping
Server-managed sessions and authentication
Many extraction tools fail completely when pulling data behind login walls. Standard scripts initiate a fresh, clean session on every single HTTP request. Security systems detect this robotic behavior. They lock the user profile indefinitely.
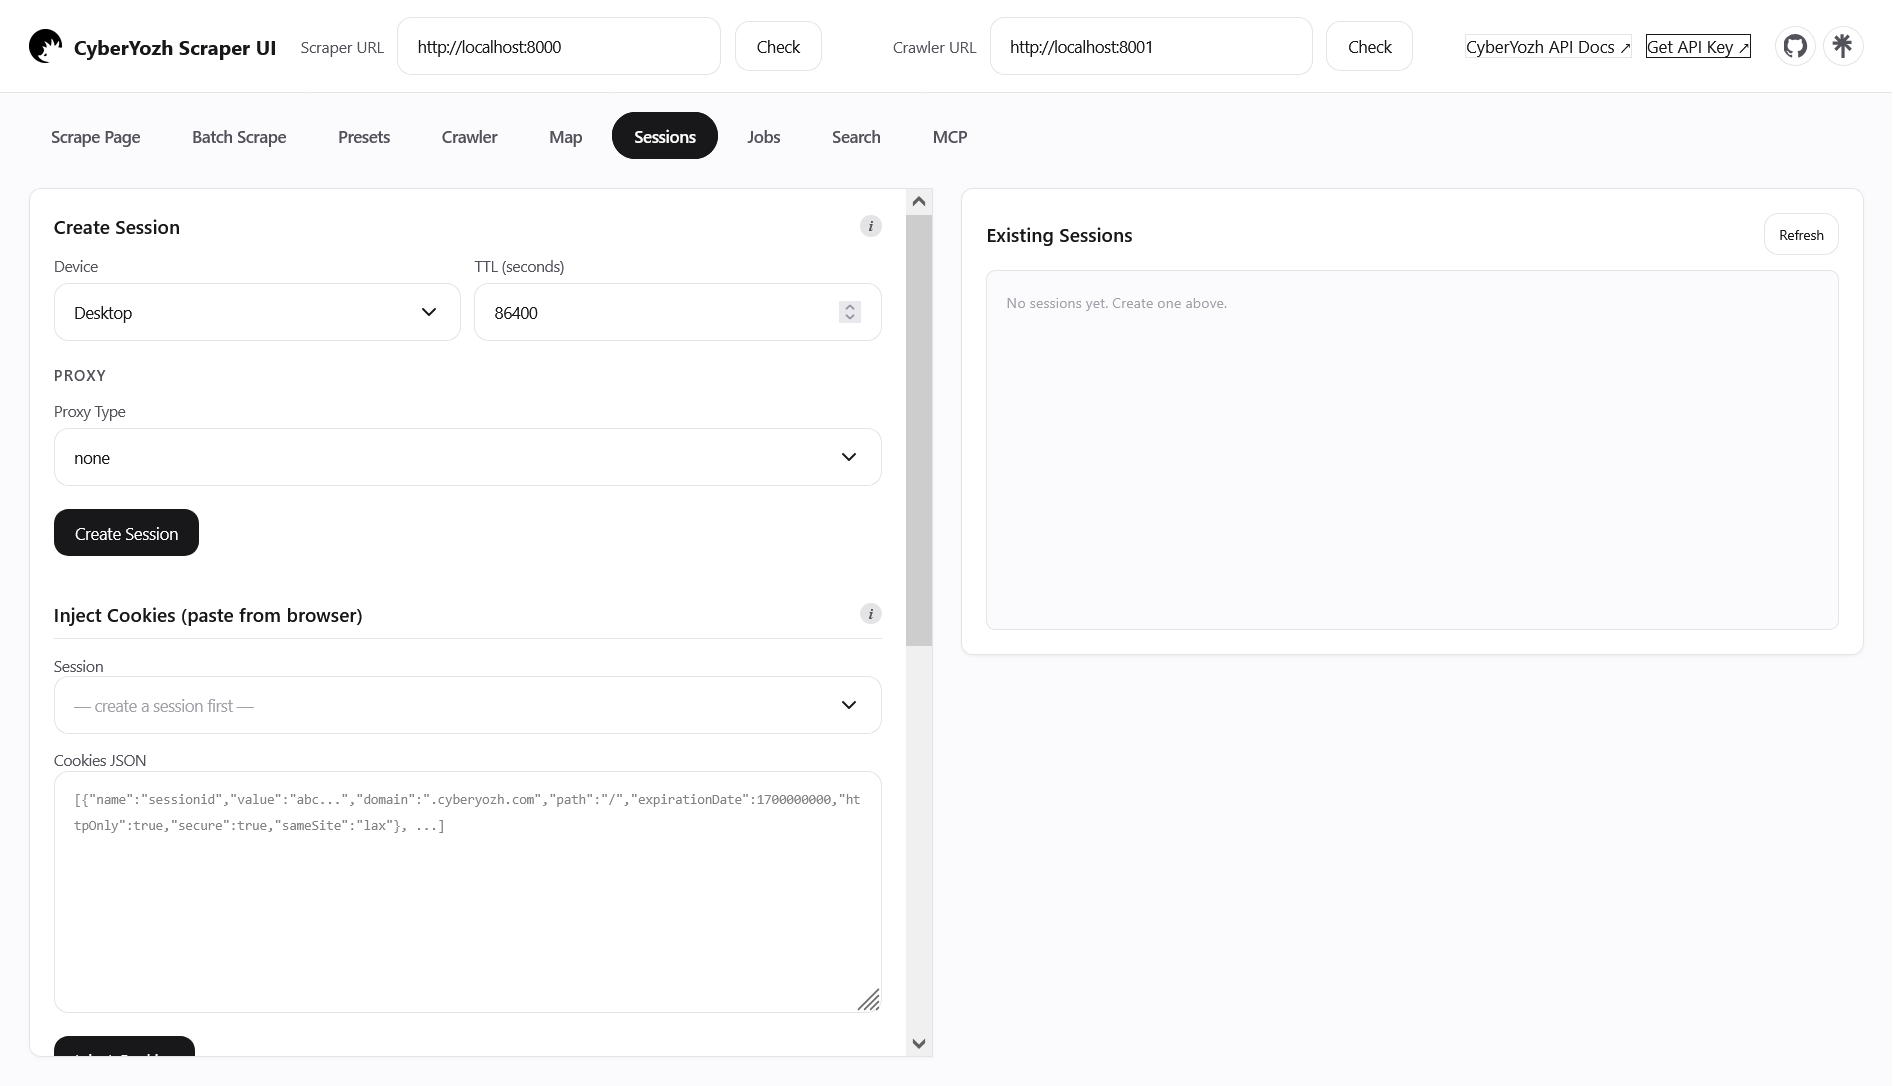
The Yozh Scraper platform solves this through server-managed sessions. You inject active browser cookies directly into the visual interface. The server preserves this context carefully. Your no code web scraper acts exactly like an authenticated, returning user. It navigates protected profiles smoothly.
👉 Get open-source Yozh Scraper on GitHub
How to scrape dynamic websites without coding using AI
Yozh Scraper is an open-source platform that eliminates manual DOM inspection and JSON payloads. The backend utilizes a native Playwright browser engine on port 8000, while the frontend operates as a Node.js visual studio on port 7000.
You formulate your request in natural language. The AI generator analyzes the markup and creates the correct extraction schema.
The platform features an AI self-healing parser function. Target platforms mutate their HTML constantly. A standard no code web scraper throws a fatal error when a field returns empty. Yozh Scraper intercepts the control flow, reads the raw HTML structure, and extracts the missing data automatically. The platform also includes a synchronous Search API to parse Google, Bing, and Yandex results instantly, plus a Real-time sitemap visualization module that maps site structures via Server-Sent Events.
👉 Datacenter proxies: extreme speed for automated API requests
MCP integration and LLM-ready datasets
Automation workflows depend heavily on large language models today. Neural networks struggle to process noisy HTML code efficiently. They hallucinate rapidly. They lose critical context. Because of this, no code web scraping for LLM markdown datasets has become a primary industry standard.
Yozh Scraper includes a highly capable built-in content filtering engine. It strips out ad blocks, navigation panels, and complex footers automatically. It outputs clean text in strict Markdown format. This structured data fits perfectly into an LLM context window.
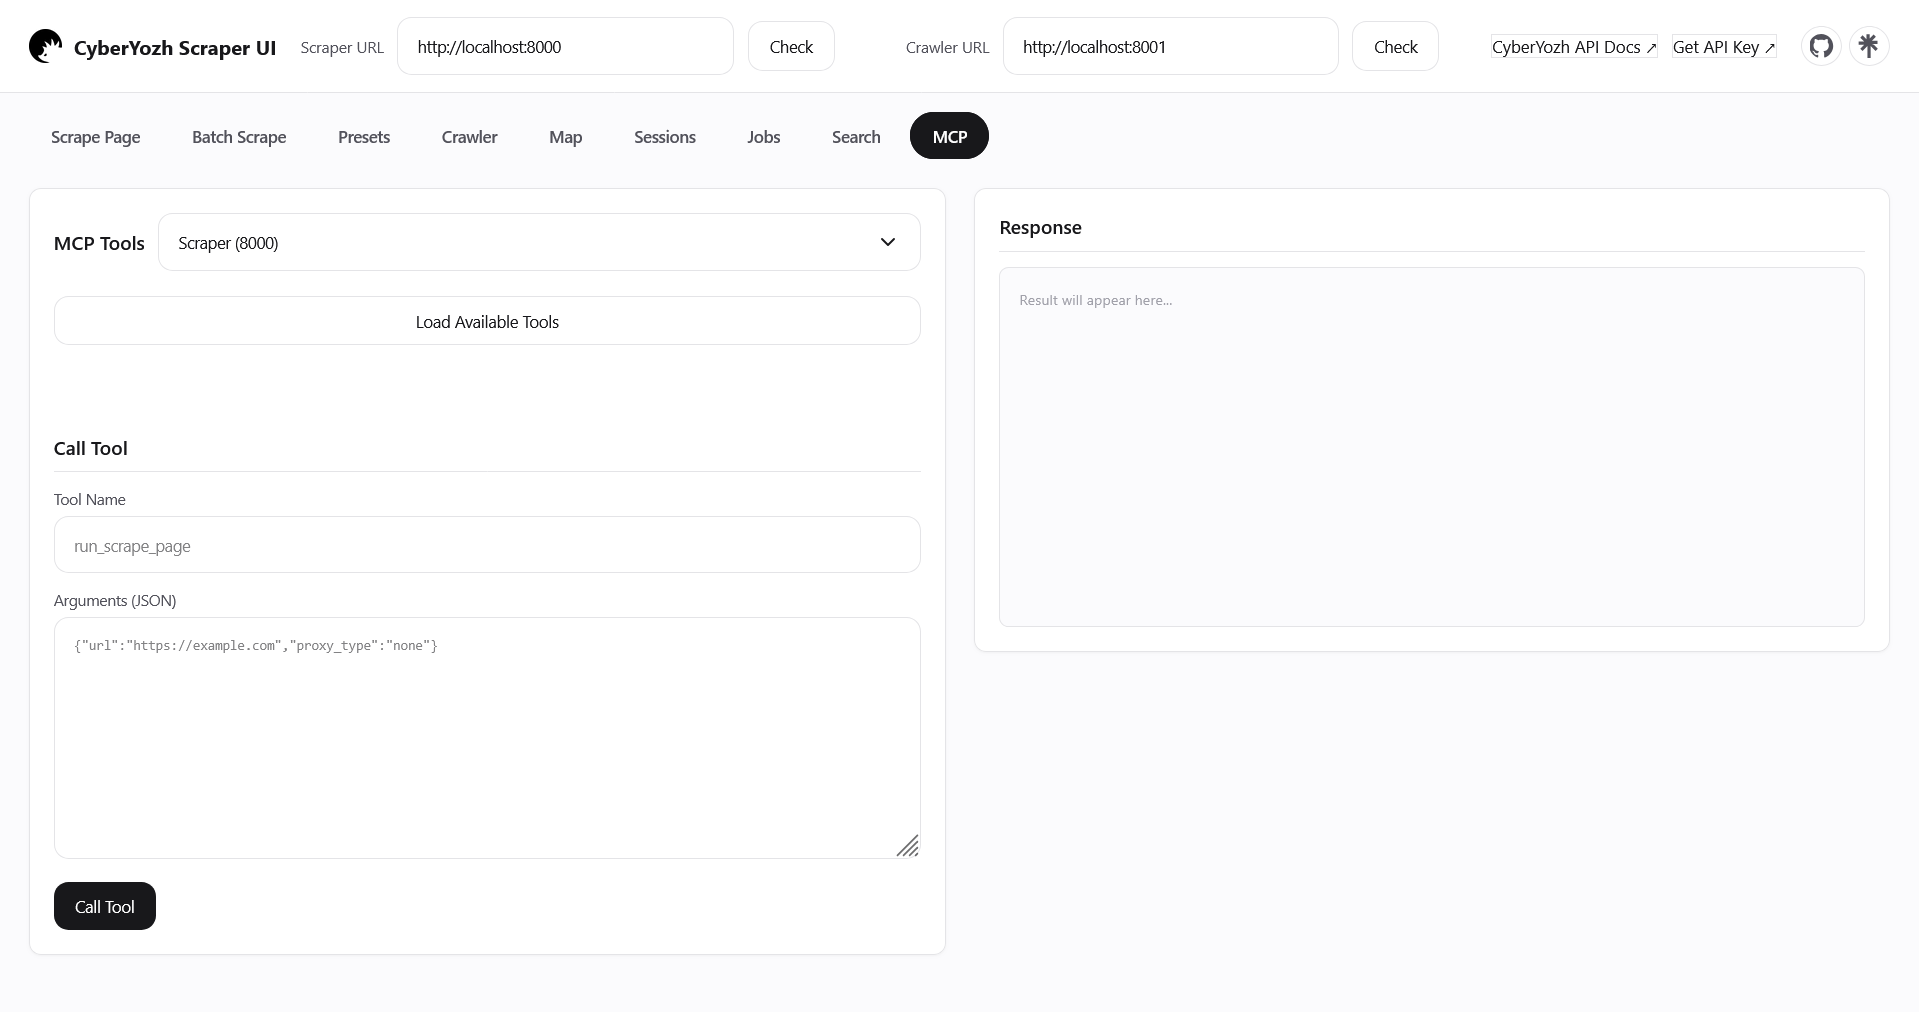
The platform provides native Model Context Protocol (MCP) integration. The backend mounts an MCP endpoint via Streamable HTTP, exposing tools like run_scrape_page and create_crawl natively. Developers configure their Claude Desktop or LangChain adapters to send commands directly. The agent plans data extraction tasks autonomously, calls Yozh Scraper, and analyzes the results without requiring any middleware code. The visual studio features a dedicated MCP Inspector tab for rapid agent debugging.
Practical deployment scenarios
Visual parsing capabilities open the door to complex business operations.
E-commerce Price Intelligence. Marketplace sellers configure a visual crawler for hourly product scans. Rotating residential proxies allow you to aggregate prices across regions without triggering anti-fraud systems. You analyze competitor ratings effortlessly. You track inventory dynamics without triggering anti-bot systems.
B2B Lead Generation. Automation tools scan business directories continuously. The software aggregates company names and exact contact numbers. Thanks to JavaScript rendering, the tool extracts data hidden behind interactive elements. You easily retrieve phone numbers concealed by dynamic buttons.
Building LLM Datasets. Research teams use crawler functions for heavy batch scraping operations. They process extensive news portals and corporate blogs. The system converts thousands of web pages into formatted Markdown documents automatically.
Real Estate Analytics. Property agencies deploy parsers to monitor local classifieds constantly. Static ISP proxies simulate local user behavior perfectly. This setup guarantees authentic data retrieval without any regional pricing distortions.
Identity management and Fraud Score verification
Data extraction pipelines often hit verification walls unexpectedly. Target platforms demand SMS codes to proceed. CyberYozh App provides virtual numbers for over 700 global websites. You can rent numbers from real local operators to overcome regional limits rapidly.
👉 Virtual numbers: register profiles using authentic ISP networks
You can also issue virtual tokenized cards instantly. These cards integrate with Apple Pay and Google Pay natively. You set spending limits and control balances from a single dashboard. They work flawlessly for SaaS subscriptions and digital goods purchases.
👉 Virtual bank cards: fund your SaaS subscriptions
Before launching aggressive extraction scripts, check your IP reputation with the Anti-Fraud Checker. You clearly see your digital footprint through the eyes of enterprise firewalls. Need to scale your data operations further? Visit CyberYozh Data for more scraping and automation tools from CyberYozh. You will find highly efficient solutions for any data extraction task.
👉 Anti-fraud checker: view your digital footprint before scraping
FAQs about no code web scrapers
How does a visual web scraping tool work?
It utilizes a backend browser engine like Playwright operating on port 8000. It renders the dynamic page visually. You click on elements, and the system generates the required CSS selectors automatically.
How to overcome cloudflare no code web scraper challenges?
You must deploy a tool that perfectly spoofs TLS fingerprints. Pair it with high-trust mobile or residential ISP proxies to avoid CAPTCHAs completely during data collection.
Why use a no code web scraper instead of Python scripts?
Hardcoded Python scripts break immediately when websites change their layout. AI-powered no code tools utilize self-healing algorithms to adapt to DOM changes automatically.
What is visual point-and-click data extraction?
It is a simplified method of selecting web elements visually. The software translates your screen interactions into a robust scraping algorithm without any programming required.
Can an automated web scraper no code platform handle infinite scrolling?
Yes. The platform simulates natural human scrolling behavior. It waits patiently for JavaScript to render new items before continuing the extraction loop.
How do I export my LLM-ready datasets?
You can download your structured files directly via CSV export. You can also utilize API integrations to push JSON payloads straight into your corporate database.